The Infrastructure Data Problem Behind Every Licensing Risk
Almost every licensing exposure we review traces back to the same root: not a missing contract clause, not a misread metric, but a gap in the infrastructure data underneath the position. A host nobody recorded the CPU model for. A cluster membership that changed after the last inventory pull. A hypervisor upgrade that nobody flagged as a licensing event. The rule or the entitlement was usually known; the estate it had to be applied to was not.
This is the pattern behind the specific traps covered elsewhere on this blog, and it is worth naming directly, because the fix is the same in every case: the data has to be current, complete, and structured the way the licensing rule needs it, not the way the inventory tool happened to export it.
The same gap, three different rules
- Oracle's core factor table is applied per host, to the physical CPU model, not the VM's vCPUs. Get the CPU model wrong, or miss a cluster member, and the factor is applied to the wrong number of cores on the wrong boundary. See the core factor table explained.
- Oracle's partitioning policy decides whether a license covers one VM or an entire cluster, and that decision depends entirely on which hypervisor is running and how the cluster is configured, data that changes every time infrastructure changes and inventory does not. See hypervisor choice and Oracle licensing.
- Red Hat's Virtual Datacenter subscriptions are bought on the host socket-pair and cover unlimited guests on it, so the gap hides at the host level, in a cluster that grew by a node nobody counted. See Red Hat VDC: hosts, guests and the unregistered systems.
Three vendors, three different rules, one shared failure mode: the licensing logic is correct and the infrastructure facts it runs on are stale, incomplete, or scattered across tools that do not agree with each other.
Why this keeps happening
Infrastructure inventory and license management have historically been built by different teams for different reasons. The CMDB exists for change management and incident response; it records what exists, not what a specific vendor's contract terms need to know about it. A discovery tool built for security or asset management catalogues software installs and hardware, but rarely the cluster membership, CPU model consistency, and hypervisor configuration that a partitioning policy actually keys on. Neither was built to answer "is this host in scope for this Oracle license," and both go stale the moment infrastructure changes without a corresponding update.
The result, covered from the reporting side in why your software intelligence is just another reporting layer, is a familiar one: a dashboard that reports what the last import contained, not what the estate is doing today, leaving the interpretation work, closing the gap between the report and the actual current state, to whoever has to answer for the position.
What the data actually needs to carry
- Physical facts, not just logical ones. CPU model and physical core count per host, not just vCPU allocations, because most vendor rules key on the physical layer.
- Cluster and hypervisor context. Which hosts belong to which cluster, on which hypervisor, updated as clusters grow or hosts move, not as of the last manual inventory.
- Lifecycle timestamps. When a host was provisioned, when a subscription or registration happened, and whether the two line up: the gap between an install date and a subscription date is exactly where backdated exposure hides.
- One view across the estate, not one per vendor. A host that shows up correctly in the Oracle-focused tool and the Red Hat-focused tool separately still leaves the cross-checks, is this host's cluster the same set in both records, to a person reconciling two exports by hand.
Closing the gap without a new collection project
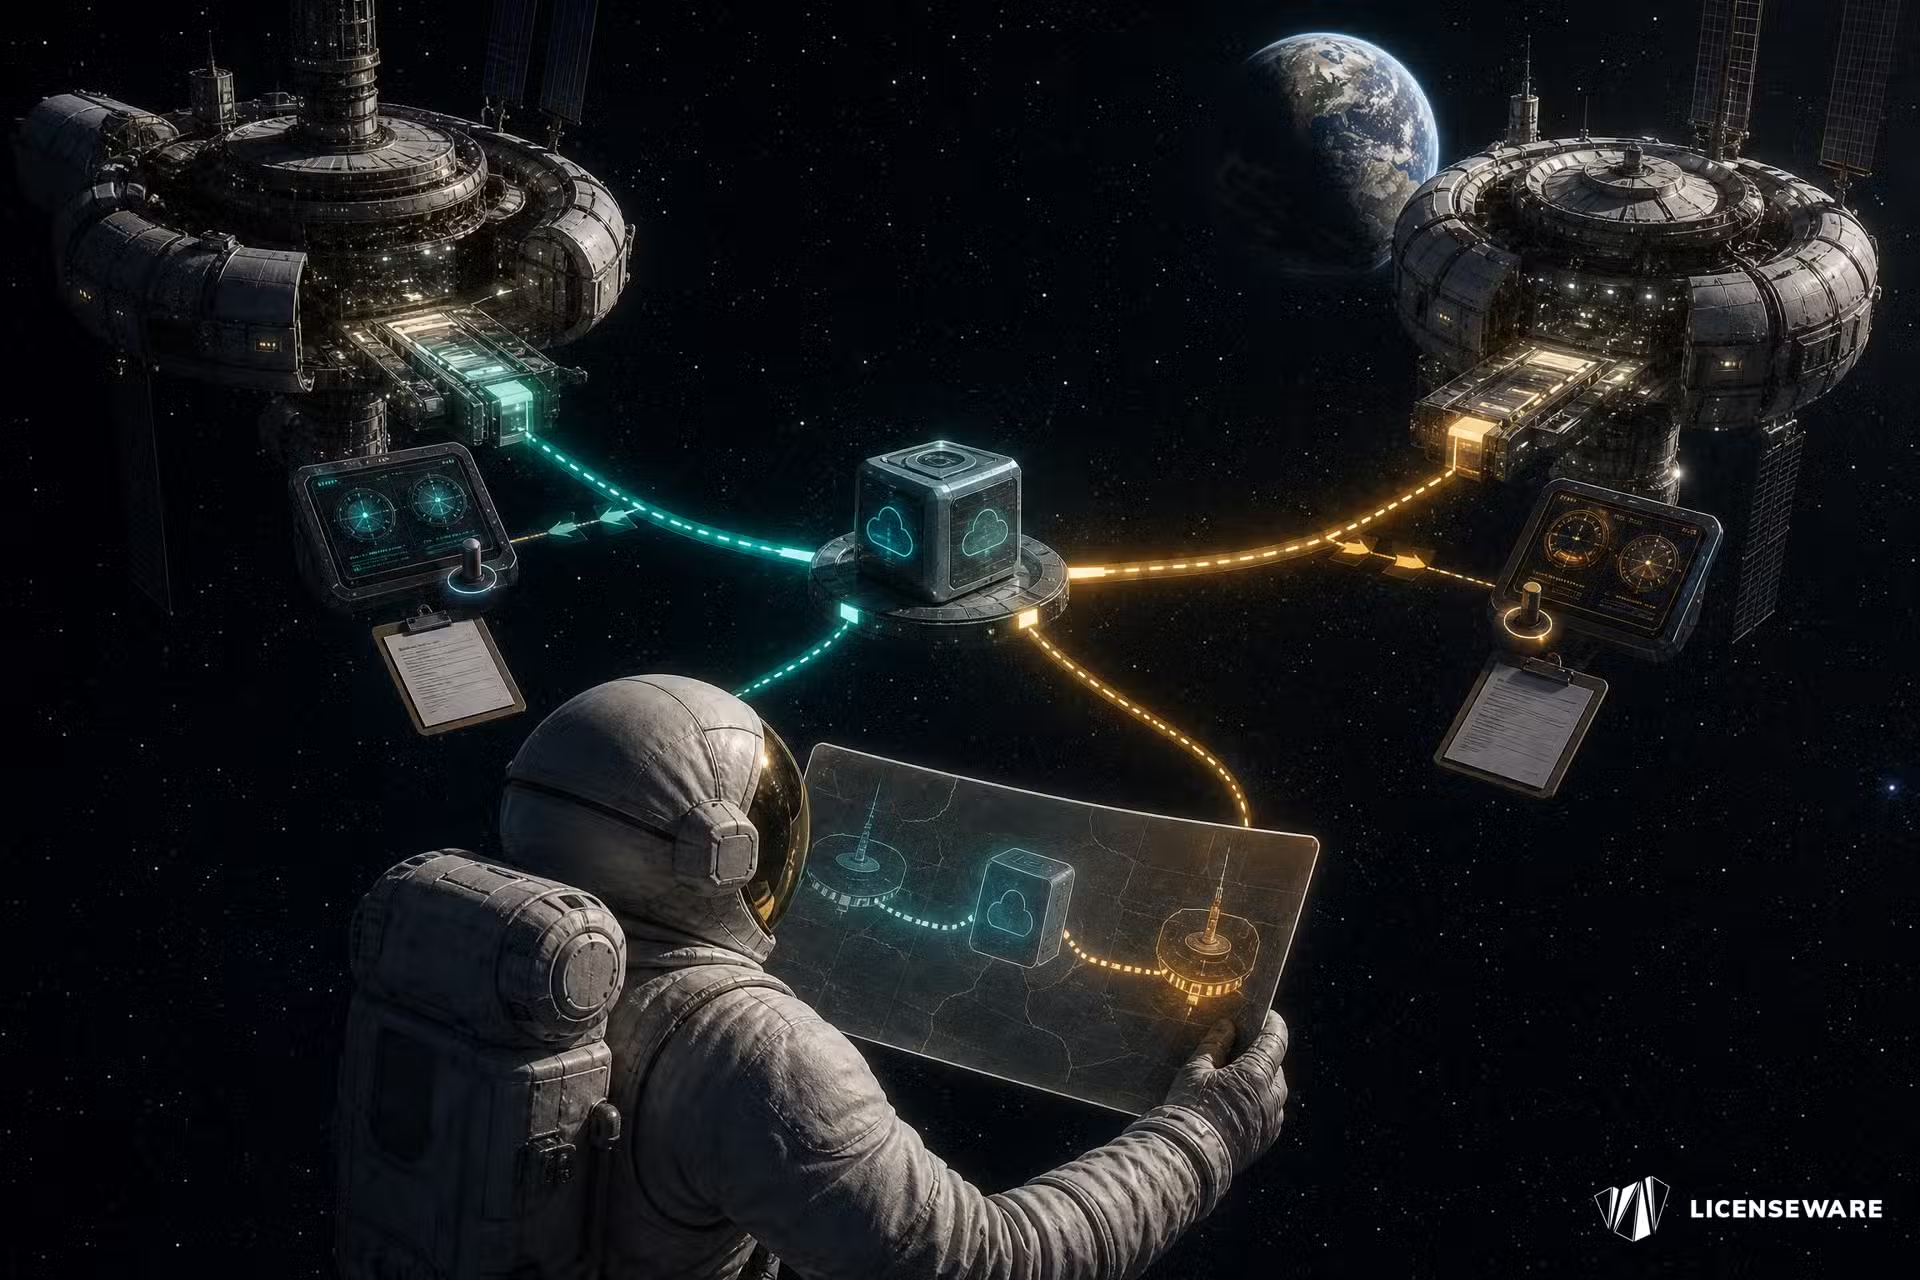
The data most of this needs already exists somewhere: a CMDB, an existing discovery tool, hypervisor management consoles, cloud provider APIs. The problem is rarely that nobody is collecting infrastructure data; it is that nothing normalizes it into the shape a licensing rule needs and keeps it current as the estate changes. Infrastructure Mapper is built for exactly that layer: it connects to the discovery and virtualization tools already in place, resolves hosts, CPU models, and cluster membership into one current record, and feeds that record to the vendor-specific apps, Oracle, Red Hat, Microsoft, that apply the licensing rules on top of it.
That is the practical shape of the fix: the licensing rules do not need to be simpler, and most vendors are not going to simplify them. What changes the outcome is infrastructure data that is complete, current, and structured once, so every rule that depends on a host, a cluster, or a CPU model is applied to a fact instead of a guess.
Checklist
- CPU model and physical core count recorded for every host running licensed software, not just vCPU counts.
- Cluster membership and hypervisor current, not pulled from the last manual inventory.
- Install and registration timestamps captured and checked against each other.
- One infrastructure record feeding every vendor-specific licensing check, not a separate export per vendor.